
HOW TO // AI — CERT · AWS MLA-C01
Pass the AWS ML Engineer Associate — the First Time
301 original practice questions weighted to the official MLA-C01 blueprint, with a plain-English explanation on every single one.
Start the free quiz — no signup →10 free questions now · 10 more with your email · the full bank from $12 a month
Claude AI Tutor included with Pro — miss a question and it explains exactly why, in plain English, until it clicks.
What this set covers. These questions follow the MLA-C01 blueprint, which AWS now offers only in Japanese, Korean and Simplified Chinese. In English, the only version you can book is the MLA-C02 beta (exam code ME1-C02: $75, 85 questions, 170 minutes, one attempt), so English test-takers should use our MLA-C02 practice questions. MLA-C02 adds generative AI, agentic AI and foundation model workloads. AWS’s certification blog dates the standard MLA-C02 to January 14, 2027, though the exam page still lists GA as TBD. See what changes in MLA-C02.
Practice questions are the fastest way to get ready for the AWS ML Engineer Associate (MLA-C01) exam: they show how concepts are tested, surface your gaps, and make exam day feel familiar. Every question below comes with an explanation of why the answer is right.
How these questions were made. Every question here is original. HOW TO // AI writes them from AWS’s public MLA-C01 exam guide and maps each one to a domain in its blueprint. They are not real exam questions: real exam content is confidential for every candidate, and we never use exam recall or dumps.
What AWS’s public exam guide covers
Everything in this section comes from AWS’s public exam guide, not from the exam itself.
| Questions | 65 (50 scored + 15 unscored) |
|---|---|
| Time limit | 130 minutes |
| Price | $150 USD |
| Delivery | Pearson VUE; test center or online proctored |
| Scoring | Scaled 100-1000; 720 to pass |
| Validity | 3 years |
| Prerequisites | None required; ~1 year of ML/SageMaker experience recommended |
| Language | Japanese, Korean and Simplified Chinese (English ended September 28, 2026; English test-takers take the MLA-C02 beta) |
Our question set is weighted to the blueprint:
| Domain | Weight | What it covers |
|---|---|---|
| Data Preparation for ML | 28% | Ingest, store, transform, and validate data for ML. Covers S3 storage, Glue/DataBrew and EMR/Spark transforms, Athena queries, streaming ingestion with Kinesis/Firehose/MSK, feature engineering with SageMaker Data Wrangler and Feature Store, labeling with Ground Truth, and governance with Lake Formation, handling issues like class imbalance and data quality. |
| ML Model Development | 26% | Choose, train, and evaluate models. Includes selecting built-in algorithms or JumpStart models, SageMaker training jobs, Automatic Model Tuning and Autopilot, tracking with Experiments, debugging with Debugger and bias/explainability checks with Clarify, and using metrics (accuracy, precision, recall, F1, AUC, RMSE) while managing overfitting and underfitting. |
| Deployment and Orchestration of ML Workflows | 22% | Deploy models and automate pipelines. Covers real-time, serverless, and asynchronous endpoints, Batch Transform, multi-model endpoints and auto scaling, plus orchestration with SageMaker Pipelines, Step Functions, EventBridge, and CI/CD via CodePipeline, infrastructure as code with CloudFormation/CDK, and container images in Amazon ECR. |
| ML Solution Monitoring, Maintenance, and Security | 24% | Monitor, maintain, and secure ML solutions in production. Includes SageMaker Model Monitor for data and model quality drift, observability with CloudWatch and CloudTrail, cost and performance optimization, and security through IAM, KMS, VPC, Secrets Manager, PrivateLink, and Macie for sensitive data. |
Take the free practice quiz
Start with 10 free questions — read the explanation after each — then unlock 10 more with your email. No account needed to begin.
FREE PRACTICE QUIZ
Try 10 free MLA-C01 practice questions
Answer at your own pace. Every question shows the correct answer and a plain-English explanation, and that's where the learning happens. Unlock 10 more questions free at the end.
Read the 10 free MLA-C01 questions as text, with answers and explanations
A team trains SageMaker models on a 4 TB tabular dataset stored as gzip-compressed CSV in Amazon S3. Analysts also run frequent Amazon Athena queries that scan only 6 of the 80 columns. Which change to the storage format will MOST reduce both Athena scan cost and SageMaker data-loading time?
- A. Convert the data to a single uncompressed JSON Lines file
- B. Re-store the data as RecordIO-protobuf shards
- C. Keep CSV but increase the gzip compression level
- D. Convert the data to Apache Parquet with Snappy compression
Answer: D. Parquet is a columnar format, so Athena reads only the 6 needed columns instead of scanning all 80, and Snappy-compressed Parquet is splittable for parallel reads. JSON Lines is row-oriented and verbose, increasing scan size. RecordIO-protobuf suits certain built-in algorithms but is not queryable by Athena and does not enable columnar pruning. Higher gzip levels do not enable column pruning, and a single gzip CSV is not splittable.
Clickstream events arrive continuously and must be delivered to Amazon S3 as Parquet, partitioned by event date, with no application code to manage and built-in buffering and format conversion. The team wants the simplest fully managed pipeline. Which AWS service should they use?
- A. Amazon Kinesis Data Streams with a custom consumer running on Amazon EC2
- B. AWS Glue streaming job writing micro-batches to S3
- C. Amazon Data Firehose with record format conversion to Parquet and dynamic partitioning
- D. Amazon MSK with a self-managed Kafka Connect S3 sink
Answer: C. Amazon Data Firehose (formerly Kinesis Data Firehose) is fully managed, buffers records, can convert JSON to Parquet, and supports dynamic partitioning to S3 with no servers to run. Kinesis Data Streams plus a custom EC2 consumer requires you to build and operate the delivery and conversion logic. MSK with Kafka Connect is self-managed and operationally heavier. A Glue streaming job is more code and infrastructure than needed for straightforward delivery to S3.
A distributed SageMaker training job needs a shared POSIX file system that many GPU instances can mount simultaneously for very high-throughput, low-latency reads of training data already staged from S3. Which storage option BEST fits this requirement?
- A. Amazon S3 accessed over the public endpoint
- B. Amazon S3 Glacier Instant Retrieval
- C. Amazon EFS Infrequent Access storage class
- D. Amazon FSx for Lustre linked to the S3 bucket
Answer: D. FSx for Lustre is a high-performance, POSIX-compliant parallel file system that integrates with S3 and is purpose-built for high-throughput ML and HPC training across many instances. EFS is POSIX but delivers lower throughput than Lustre for large-scale GPU training, and the IA class is for cost savings on rarely accessed files. S3 and Glacier are object stores, not shared POSIX file systems.
A team wants a visual, low-code tool to profile a CSV dataset, identify missing values and outliers, and apply 250+ prebuilt cleaning and normalization transformations without writing Spark or pandas code. Which AWS service is designed for this?
- A. AWS Lambda
- B. Amazon EMR on EC2
- C. Amazon Athena
- D. AWS Glue DataBrew
Answer: D. AWS Glue DataBrew is a visual data-preparation tool with hundreds of prebuilt transformations and built-in profiling for missing values and outliers, requiring no code. Athena queries data with SQL but does not provide a visual cleaning UI. EMR requires writing Spark code, and Lambda is general-purpose compute, not a data-prep tool.
A high-cardinality categorical column 'product_id' has 50,000 distinct values and will feed a gradient-boosted tree model. One-hot encoding would create 50,000 sparse columns. Which encoding approach is the MOST appropriate to control dimensionality while preserving predictive signal?
- A. Label encoding that assigns arbitrary sequential integers used directly as the feature
- B. Dropping the column entirely because it is high cardinality
- C. Target (mean) encoding computed only from the training split
- D. One-hot encoding with all 50,000 categories retained
Answer: C. Target encoding replaces each category with a statistic (such as the mean of the target) and keeps the feature one-dimensional, which works well for very high-cardinality columns; computing it only on the training split avoids leakage. One-hot at 50,000 levels explodes dimensionality. Arbitrary integer label encoding imposes a false ordinal relationship that misleads many models. Dropping the column discards potentially useful signal.
A data scientist has a tabular dataset in Amazon S3 with a labeled target column and wants SageMaker to automatically explore feature preprocessing, candidate algorithms, and hyperparameters to produce a leaderboard of trained models with minimal code. Which SageMaker capability is the BEST fit?
- A. Amazon SageMaker Debugger
- B. Amazon SageMaker JumpStart foundation models
- C. Amazon SageMaker Model Monitor
- D. Amazon SageMaker Autopilot (AutoML)
Answer: D. Autopilot (AutoML) automatically handles preprocessing, algorithm selection, and hyperparameter tuning on tabular data, producing a ranked leaderboard of candidate models. JumpStart provides pretrained foundation/proprietary models rather than AutoML over your tabular data. Debugger inspects training jobs for issues, and Model Monitor watches deployed endpoints for drift, neither of which builds candidate models.
A retail company must forecast daily demand for thousands of SKUs across many stores, where some items have only a few months of sales history. The team wants a managed approach that captures cross-series patterns rather than fitting one model per SKU. Which approach best frames and solves this problem?
- A. Treat it as binary classification using the SageMaker XGBoost built-in algorithm
- B. Treat it as a time-series forecasting problem and use the SageMaker DeepAR built-in algorithm
- C. Treat it as clustering using the SageMaker K-Means built-in algorithm
- D. Treat it as anomaly detection using the SageMaker Random Cut Forest built-in algorithm
Answer: B. This is a time-series forecasting problem, and DeepAR is designed to train a single global model across many related time series, which helps cold-start SKUs with little history by learning shared patterns. XGBoost classification, K-Means clustering, and Random Cut Forest anomaly detection address fundamentally different problem types and would not produce per-SKU demand forecasts.
A team wants to build a customer-support summarization feature. They want to start from a high-quality pretrained large language model deployable on SageMaker, then optionally fine-tune it on their own ticket data. Which SageMaker capability most directly provides access to such pretrained foundation models?
- A. Amazon SageMaker JumpStart
- B. Amazon SageMaker Ground Truth
- C. Amazon SageMaker Clarify
- D. Amazon SageMaker Feature Store
Answer: A. SageMaker JumpStart provides a catalog of pretrained foundation models (including LLMs) that can be deployed and fine-tuned on SageMaker, making it the direct fit for an NLP summarization use case. Feature Store stores features, Ground Truth labels data, and Clarify analyzes bias and explainability, none of which provide pretrained foundation models.
During a SageMaker training job for a neural network, the model fits the training data well but the validation loss begins increasing while training loss keeps decreasing. The team wants the training job to automatically stop and keep the best checkpoint when validation stops improving. Which technique should they configure?
- A. Increase the learning rate used in training
- B. Remove the validation channel from the job
- C. Switch across to a larger training instance type
- D. Enable early stopping on the validation metric
Answer: D. Rising validation loss alongside falling training loss is overfitting, and early stopping halts training when the monitored validation metric stops improving, retaining the best model. Increasing the learning rate or scaling up instances does not address overfitting, and removing the validation channel would eliminate the very signal needed to detect the problem.
A team uses SageMaker Automatic Model Tuning (AMT) to find good hyperparameters for an XGBoost model. They want to minimize the number of training jobs while letting the tuner learn from completed jobs to choose promising next configurations. Which tuning strategy best meets this goal?
- A. Grid search over the space
- B. Random search of the space
- C. Bayesian optimization search
- D. Manual search by the team
Answer: C. Bayesian optimization builds a probabilistic model of the objective and uses results from completed jobs to select promising next hyperparameter configurations, typically reaching good results with fewer training jobs. Grid and random search do not learn from prior results, and manual search is not an AMT strategy and is inefficient.
Want more? Finish the quiz above to unlock 10 more free questions, or open the full MLA-C01 practice app.
After the free 20
Practice the full MLA-C01 bank, timed like exam day
HOW TO // AI CERT has 301 original MLA-C01 practice questions written from AWS’s public exam guide. You also get timed mock exams, an AI tutor powered by Claude that explains every miss, and a readiness score that tells you when to book. Pro is $12 a month, or $39 for the whole year, and covers every exam we offer. Start with a free account. 14-day refund.
These are original practice questions, not real exam questions. No brain dumps, nothing copied from real exams.
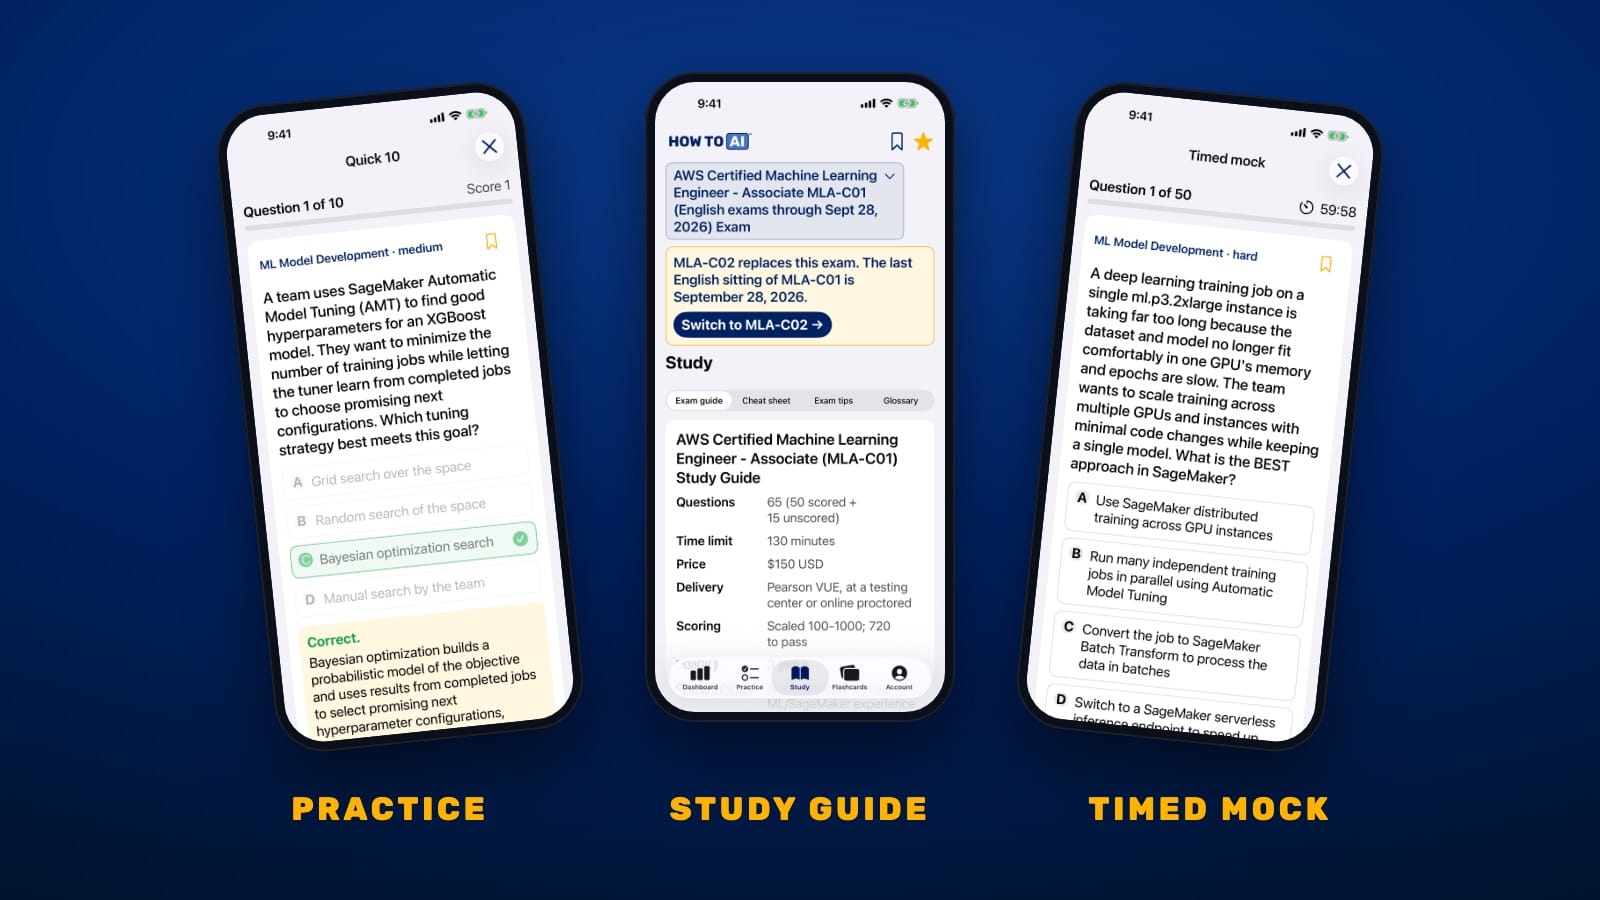
Study this exam on your phone
HOW TO // AI CERT has 6,151 original practice questions across 18 AI and cloud certifications, with plain-English explanations on every answer, full timed mock exams, weak-area drills, and an AI tutor powered by Claude. Free to download, with a free question set for every exam.
Free AWS ML Engineer Associate (MLA-C01) study guide & cheat sheet
Prefer to study first? The free AWS ML Engineer Associate (MLA-C01) study guide has the exam breakdown, a topic cheat sheet, and a full glossary — no sign-up.
How to prepare
Read the official exam objectives on the AWS Machine Learning Engineer – Associate page, take a practice set above, then focus your studying on the domains where you missed questions rather than re-reading everything. Pair it with the study guide for the concepts.
HOW TO // AI is not affiliated with or endorsed by Amazon Web Services. AWS Certified Machine Learning Engineer – Associate and MLA-C01 are certifications of Amazon.com, Inc. or its affiliates; we reference them descriptively. All questions are original.
Practice for every AI & cloud cert
- NVIDIA NCA-AIIO practice questions
- NVIDIA NCA-GENL practice questions
- AWS AIF-C01 practice questions
- AWS MLA-C02 practice questions
- Microsoft AI-901 practice questions
- Microsoft AI-103 practice questions
- VMware VCP-VCF Administrator practice questions
- CompTIA AI Fundamentals practice questions
- Google Cloud Generative AI Leader practice questions
- Oracle OCI AI Foundations practice questions
- CertNexus AIP-210 practice questions
- Anthropic CCAO-F practice questions
- Anthropic CCDV-F practice questions
- Anthropic CCAR-F practice questions
- Anthropic CCAR-P practice questions
- Databricks GenAI Engineer Associate practice questions
- Salesforce Agentforce Specialist practice questions
- CompTIA SecAI+ practice questions
- All AI & cloud exam prep →
Frequently asked questions
How many questions are on the AWS ML Engineer Associate (MLA-C01) exam, and what do I need to pass?
MLA-C01 has 65 questions (50 scored plus 15 unscored) in 130 minutes, and you need a scaled score of 720 out of 1,000. It is delivered by Pearson VUE, online proctored or at a test center. Since September 28, 2026 it is offered only in Japanese, Korean and Simplified Chinese; in English you take the MLA-C02 beta instead (85 questions, 170 minutes).
How much does the AWS ML Engineer Associate exam cost?
MLA-C01 costs $150 USD where it is still offered. The English MLA-C02 beta (exam code ME1-C02) costs $75 and allows one attempt. Prices exclude tax and can vary by region; you register through the AWS Certification site.
How should I prepare for the AWS ML Engineer Associate exam?
First check which version you are booking: English test-takers now sit the MLA-C02 beta, so use our MLA-C02 practice questions. AWS's target candidate has about a year of hands-on ML and Amazon SageMaker experience. Study the official exam guide, then work through practice questions to find and fix weak spots; our 301-question MLA-C01 bank follows the published domain weights.
Are HOW TO // AI CERT's AWS ML Engineer Associate questions real exam questions?
No. All 301 of our MLA-C01 practice questions are original, written from the published exam objectives, and we never copy, leak or reproduce real exam content (brain dumps), which would violate AWS's policies and would not teach you the material. Every question comes with a plain-English explanation so you learn the concept, not just the answer.
Is HOW TO // AI CERT affiliated with Amazon Web Services (AWS)?
No. HOW TO // AI CERT is an independent study resource and is not affiliated with, authorized by, endorsed by, or sponsored by Amazon Web Services (AWS). All product and exam names are trademarks of their respective owners; we reference them only to describe what our practice questions cover.
Can I try AWS ML Engineer Associate practice questions for free?
Yes. You can practice a free set of MLA-C01 questions with no sign-up required, then unlock more by email. Pro unlocks the full 301-question bank plus timed mock exams, flashcards, spaced-repetition review, a readiness score, and an AI tutor that explains any question, from $12/month; one subscription covers every certification we offer.