
NVIDIA NCA-GENL (Gen AI & LLMs) Study Guide & Cheat Sheet
A free study guide for the NVIDIA NCA-GENL (Gen AI & LLMs) exam — exam facts, the domain breakdown, study tips, a topic cheat sheet, and a full glossary. No sign-up needed. For a week-by-week schedule, follow the 3-week NCA-GENL study plan.
Ready to practice? Take the free NVIDIA NCA-GENL (Gen AI & LLMs) practice quiz → · Get the full exam prep →
Who NCA-GENL is for
NCA-GENL is NVIDIA’s associate exam for generative AI and large language models, and it leans developer. Most of it sits in development, experimentation and the data work behind them, which is what separates it from the beginner cloud certs: less “what is a foundation model”, more “what would you change about this pipeline”. If your job is the GPU platform rather than the models, NCA-AIIO fits better, and this comparison lays the two side by side.
As with the rest of NVIDIA’s associate line, the result comes back as pass or fail with no score attached. You cannot aim for a number, so the plan is to leave no domain weak.
How to use this guide
- Follow the domain weights, not your interests. The development and experimentation share is the biggest, and it is where people who came to LLMs through chatbots are thinnest.
- Read the tips for how NVIDIA frames its scenarios.
- Use the cheat sheet as a checklist and flag anything you could not explain to a colleague.
- Practise under time with our free NCA-GENL questions, which explain every answer.
Before you book
Read what NCA-GENL costs over time (renewal is the part people miss) and whether it is worth it. If you are tempted by shortcuts, the honest math on dumps is worth five minutes. For a schedule, see our three-week plan.
NVIDIA NCA-GENL (Generative AI LLMs) Study Guide
| Questions | 50-60 multiple choice |
|---|---|
| Time limit | 60 minutes |
| Price | $125 USD |
| Delivery | Proctored; you register and launch the exam through a Certiverse account |
| Scoring | Pass/fail |
| Validity | 2 years |
| Prerequisites | A basic understanding of generative AI and large language models |
| Language | English |
Exam domains
| Domain | Weight | What it covers |
|---|---|---|
| Core Machine Learning and AI Knowledge | 30% | The largest domain and the conceptual base for everything else. Covers the foundations of generative AI and language modeling, the transformer architecture and the attention mechanism that underpins every modern LLM, and the difference between training and inference across supervised, unsupervised and self-supervised learning. Also covers tokenization, embeddings and context windows, plus neural network and deep learning fundamentals. Roughly 15 to 18 of the 50 to 60 exam questions come from here, so it is the first place to spend study time. NVIDIA's current topic list also names hands-on skills: building RAG pipelines, chatbots and summarizers, curating and embedding content for RAG, choosing a model to create text embeddings, and using Python packages such as spaCy, NumPy and Keras for traditional ML and NLP analysis. |
| Software Development | 24% | Building and shipping LLM applications. Covers prompt engineering across zero-shot, one-shot and few-shot, chain-of-thought, system prompts and reusable templates, and retrieval-augmented generation for grounding answers in external data. Also covers the NVIDIA generative AI stack, meaning NeMo, NIM inference microservices, Triton Inference Server, TensorRT-LLM and NeMo Retriever and Guardrails, along with fine-tuning and customization through SFT, LoRA and PEFT and instruction tuning, deployment and integration, and the Python libraries you would actually reach for: PyTorch, Hugging Face and LangChain. The current topic list adds identifying the data, hardware and software components a solution needs (for example, how many GPUs a model needs at a given precision), monitoring data collection, experiments and other running processes, and Python packages for NLP and vector search such as spaCy, NumPy and vector databases. |
| Experimentation | 22% | Designing experiments and judging whether a model is any good. Covers evaluating LLMs with benchmarks, automated metrics such as perplexity, ROUGE and BLEU, and human or model-graded evaluation. Also covers experiment design and methodology, including train, validation and test splits, and the iteration loop of error analysis, targeted change and measuring whether the change actually helped. NVIDIA also places the use of human subjects in labeling and in reinforcement learning from human feedback (RLHF) in this domain. Larger than most candidates expect, and it rewards understanding why an evaluation was designed a certain way rather than which metric carries which name. It also covers testing LLM applications on real hardware and software, such as load testing an endpoint for time to first token and throughput, and weighing technologies on cost, portability, compatibility and usability. |
| Data Analysis and Visualization | 14% | Getting data ready for generative and ML workloads. Covers preprocessing and cleaning, including deduplication, normalization and handling missing values, feature engineering, and exploratory data analysis and visualization. Concrete rather than theoretical: questions here usually describe a specific defect in a dataset and ask which preparation step addresses it. NVIDIA also lists comparing models with statistical metrics such as a loss function or the proportion of explained variance (R-squared), building charts that communicate results, and spotting relationships, trends or confounding factors that could skew a conclusion. |
| Trustworthy AI | 10% | The smallest domain. NVIDIA's objectives cover the ethical principles of trustworthy AI, the balance between data privacy and data consent, using NVIDIA and other technologies to improve AI trustworthiness, and minimizing bias in AI systems. It is small and well defined, which makes it cheap to prepare and an easy 10 percent to give away by skipping it. |
Who it’s for: Associate-level practitioners — developers, data scientists, and ML engineers — who build, integrate, and deploy generative-AI and LLM applications using NVIDIA tools such as NeMo, NIM, Triton, and TensorRT-LLM.
Study & test-day tips
- Budget your time: 50 questions in 60 minutes is about 70 seconds each. Answer what you know quickly, flag the rest, and circle back so the clock never traps you on one hard item.
- The exam is conceptual, not a coding test. Know what a technology is FOR — what problem LoRA, RAG, or a NIM microservice solves — rather than memorizing exact API calls or hyperparameter values.
- Master the transformer story end to end: tokens in, embeddings, self-attention, and autoregressive token-by-token generation out. Core ML & AI Fundamentals is 30% of the exam, so this pays off most.
- Know the four ways to improve an LLM's output and when to use each: prompt engineering (cheapest), RAG (add fresh/private knowledge), fine-tuning/PEFT (change behavior), and RLHF (align to preferences).
- RAG vs fine-tuning is a classic distractor pair. RAG injects external knowledge at inference without retraining; fine-tuning bakes new behavior into the weights. Match the technique to whether the gap is knowledge or behavior.
- Memorize the evaluation metrics and what they measure: perplexity for language-model fit, ROUGE for summarization (recall-oriented), BLEU for translation (precision-oriented), plus human and LLM-as-judge for open-ended quality.
- Learn the NVIDIA gen-AI stack by job: NeMo (build/train/customize), NIM (deploy as a microservice), Triton (serve at scale), TensorRT-LLM (optimize inference), NeMo Retriever (RAG embeddings), NeMo Guardrails (safety).
- Watch for qualifier words like 'most likely', 'primary purpose', and 'best'. Two options are often defensible; the qualifier and the most specific answer pick the winner.
- Don't leave blanks — there's no penalty for guessing. Eliminate two options and choose the more specific remaining answer.
- Take the timed mock in this app at least twice and book only when you're consistently scoring 80%+. The exam is pass/fail, so aim for margin, not a coin flip.
Cheat sheet
How an LLM works
- Tokenization: text is split into tokens (subword units), each mapped to an integer ID the model can process
- Embeddings: tokens become dense vectors that capture meaning; similar concepts sit close together in vector space
- Self-attention: each token weighs the relevance of every other token in the context — the transformer's core mechanism
- Autoregressive generation: the model predicts the next token one at a time, feeding each output back as input
- Context window: the maximum number of tokens (prompt + output) the model can attend to at once
Decoding & generation controls
- Temperature: higher = more random/creative output, lower = more deterministic and focused
- Top-p (nucleus sampling): sample from the smallest set of tokens whose probabilities sum to p
- Top-k: restrict sampling to the k most probable next tokens
- Max tokens: caps the length of the generated response
- Greedy decoding: always pick the single most probable next token (deterministic, can be repetitive)
Prompt engineering
- Zero-shot: ask the task directly with no examples
- Few-shot: include a handful of input/output examples to steer format and behavior
- Chain-of-thought: prompt the model to reason step by step, improving multi-step and math problems
- System prompt: sets persona, rules, and constraints that apply across the conversation
- RAG: retrieve relevant external documents and add them to the prompt to ground answers and reduce hallucination
Customizing & aligning models
- SFT (supervised fine-tuning): further train on labeled task examples to specialize behavior
- LoRA / PEFT: parameter-efficient fine-tuning — train small added weights instead of the full model, saving compute and memory
- RLHF: reinforcement learning from human feedback aligns outputs to human preferences
- Alignment: making a model helpful, honest, and harmless via instruction tuning, RLHF, and guardrails
- RAG vs fine-tuning: RAG adds knowledge at inference; fine-tuning changes the model's learned behavior
Evaluation metrics
- Perplexity: how well a language model predicts a sample — lower is better
- ROUGE: overlap-based, recall-oriented metric for summarization quality
- BLEU: n-gram precision metric originally for machine translation
- Human evaluation & LLM-as-judge: rate open-ended quality where automatic metrics fall short
- Overfitting vs underfitting: too tailored to training data vs too simple to capture the pattern
NVIDIA gen-AI stack
- NeMo: framework to build, train, and customize LLMs and other generative models
- NIM (NVIDIA Inference Microservices): packaged, optimized model endpoints for easy deployment
- Triton Inference Server: serves models from any framework at scale with dynamic batching
- TensorRT-LLM: optimizes LLM inference (quantization, fused kernels) for low latency and high throughput
- NeMo Retriever & NeMo Guardrails: embedding/retrieval for RAG, and programmable safety/topic controls
- Foundations: CUDA, NGC catalog, RAPIDS for data, plus PyTorch, Hugging Face, and LangChain for development
Python data and NLP toolkit
- spaCy: load a trained pipeline with spacy.load, then read tokens, sentences and named entities (doc.ents); stream large volumes with nlp.pipe
- NumPy: fast array math; normalize embedding rows to unit length and one matrix product gives cosine similarity for a whole batch
- scikit-learn: classic models, metrics and cross-validation; put preprocessing such as TF-IDF and the model in one Pipeline so each fold fits only on its own training data
- Keras: high-level deep learning API; for multi-class labels stored as integers, pair a softmax output with sparse categorical cross-entropy
- RAPIDS cuDF and cuML: GPU-accelerated dataframes and ML with pandas-like and scikit-learn-like APIs
- Matplotlib: charts for analysis, such as a histogram of token counts to choose a maximum sequence length
Benchmarking LLM serving
- Time to first token (TTFT): the wait before the first output token arrives; it drives how responsive a streaming chat feels
- Inter-token latency: the average gap between output tokens once streaming has started
- Throughput: output tokens (or requests) per second across all users; it rises with concurrency until the GPU saturates, while latency keeps climbing
- AIPerf: NVIDIA's tool for load testing a model endpoint and reporting these metrics (it replaces GenAI-Perf, which is being phased out)
- Pick the highest concurrency that still meets the latency target (for example p95 time to first token), not the one with the highest raw throughput
Glossary
- Alignment
- The process of making a model's behavior helpful, honest, and harmless and consistent with human intent, typically via instruction tuning, RLHF, and guardrails.
- Attention
- A mechanism that lets a model weigh the relevance of different tokens when producing each output; self-attention is the core of the transformer.
- Autoregressive
- Generating output one token at a time, where each new token is conditioned on all the tokens produced so far.
- BLEU
- A precision-based, n-gram overlap metric originally designed to evaluate machine translation quality against reference text.
- Chain-of-thought
- A prompting technique that asks the model to reason step by step, improving performance on multi-step and reasoning tasks.
- Context window
- The maximum number of tokens (prompt plus generated output) a model can consider at once.
- CUDA
- NVIDIA's parallel computing platform and programming model that lets software run general-purpose computation on GPUs.
- Disaggregated evaluation
- Measuring a model's performance separately for each relevant subgroup (for example by language, region or demographic group) instead of only in aggregate, so a gap hidden by the overall average becomes visible.
- Embedding
- A dense numeric vector representing a token, word, or document so that semantic similarity corresponds to closeness in vector space.
- Federated learning
- Training a shared model across sites that keep their data local; only model updates are exchanged and aggregated. NVIDIA FLARE is NVIDIA's open-source framework for it.
- Few-shot prompting
- Providing a small number of input/output examples in the prompt to guide the model's format and behavior.
- Fine-tuning
- Further training a pretrained model on task- or domain-specific data to adapt its behavior.
- Hallucination
- When a model produces fluent but factually incorrect or fabricated content; RAG and grounding help reduce it.
- Hugging Face
- A popular ecosystem and library hub for sharing, loading, and running pretrained transformer models and datasets.
- Inference
- Running a trained model on new inputs to produce outputs; for LLMs, generating text token by token.
- Keras
- A high-level Python API for building and training deep learning models layer by layer.
- LangChain
- An open-source framework for building LLM applications by chaining prompts, models, tools, memory, and retrieval.
- LM Evaluation Harness
- EleutherAI's open-source framework for running standard LLM benchmarks consistently. Scores are only comparable when the task, its version and the few-shot setting match.
- LoRA
- Low-Rank Adaptation — a parameter-efficient fine-tuning method that trains small added weight matrices instead of the full model.
- Milvus
- An open-source vector database for storing embeddings and running similarity search, with a choice of index types, including GPU-accelerated ones, that trade recall, speed and memory.
- Model card
- A document published with a model that states its intended use, limitations, training data and evaluation results. NVIDIA's Model Card++ adds subcards for bias, explainability, privacy, and safety and security.
- NeMo
- NVIDIA's framework for building, training, and customizing large language models and other generative AI models.
- NeMo Guardrails
- An NVIDIA toolkit for adding programmable safety, topic, and behavior controls to LLM applications.
- NeMo Retriever
- NVIDIA's set of microservices for embedding and retrieval that power retrieval-augmented generation pipelines.
- NGC
- NVIDIA's catalog of GPU-optimized containers, pretrained models, and SDKs.
- NIM
- NVIDIA Inference Microservices — packaged, GPU-optimized model endpoints that make deploying models as APIs fast and consistent.
- NumPy
- The core Python library for fast n-dimensional array math, used underneath most ML and data tooling.
- PEFT
- Parameter-Efficient Fine-Tuning — a family of methods (including LoRA) that adapt models by updating a small fraction of parameters.
- Perplexity
- A metric for how well a language model predicts a sample of text; lower perplexity means better predictions.
- Prompt engineering
- Crafting and structuring inputs — instructions, examples, and context — to get better outputs from an LLM without changing its weights.
- PyTorch
- A widely used open-source deep learning framework for building and training neural networks, including transformers.
- Quantization
- Reducing the numeric precision of model weights (e.g., to 8- or 4-bit) to shrink memory use and speed up inference.
- R-squared
- The proportion of the variance in the target that a regression model explains. 1.0 is a perfect fit, and comparing it across models only makes sense on the same data.
- RAG
- Retrieval-Augmented Generation — retrieving relevant external documents and adding them to the prompt so the model grounds answers in current or private data.
- RAPIDS
- NVIDIA's suite of GPU-accelerated libraries for data science and data preprocessing, mirroring pandas and scikit-learn APIs.
- RLHF
- Reinforcement Learning from Human Feedback — aligning a model's outputs to human preferences using a learned reward signal.
- ROUGE
- A recall-oriented, overlap-based metric commonly used to evaluate text summarization quality against reference summaries.
- SFT
- Supervised Fine-Tuning — training a model on labeled input/output examples to specialize its behavior for a task.
- spaCy
- An open-source Python NLP library with trained pipelines for tokenization, part-of-speech tagging, dependency parsing and named entity recognition.
- TensorRT-LLM
- An NVIDIA library that optimizes large language model inference (fused kernels, quantization) for low latency and high throughput.
- Time to first token (TTFT)
- The delay between sending a request and receiving the first generated token; the main driver of how responsive a streaming chat feels.
- Tokenization
- Splitting text into tokens (often subword units) and mapping them to integer IDs that a model can process.
- Transformer
- The neural network architecture, based on self-attention, that underpins modern LLMs and most generative AI models.
- Triton Inference Server
- NVIDIA's open-source server for deploying models from any framework at scale, with features like dynamic batching.
HOW TO // AI is not affiliated with or endorsed by NVIDIA. NCA-GENL is a certification of NVIDIA Corporation; we reference it descriptively. All questions are original.
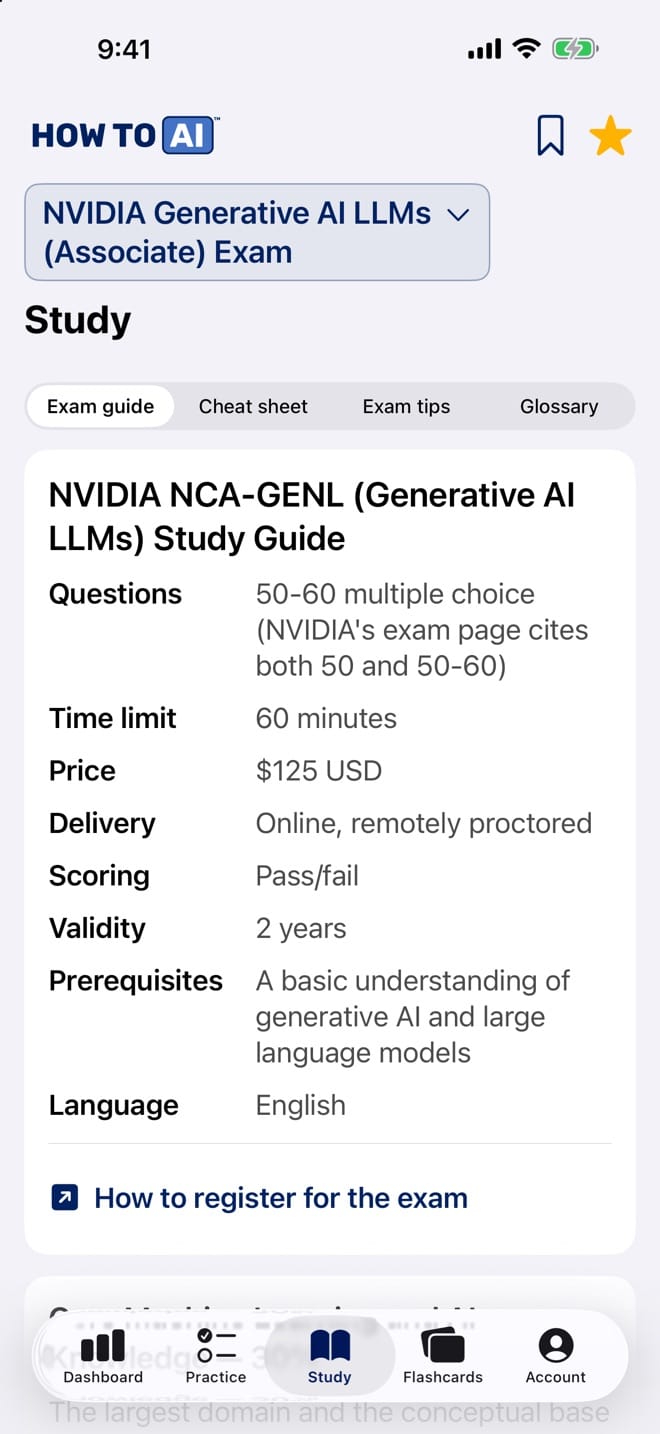
Take this guide with you
The same study guide, cheat sheet and glossary live in HOW TO // AI CERT on iPhone, next to 6,151 original practice questions, timed mock exams, flashcards and an AI tutor powered by Claude. Free to download, with a free question set for every exam.
Practice for every AI & cloud cert
- NVIDIA NCA-AIIO practice questions
- AWS AIF-C01 practice questions
- AWS MLA-C02 practice questions
- AWS MLA-C01 practice questions
- Microsoft AI-901 practice questions
- Microsoft AI-103 practice questions
- VMware VCP-VCF Administrator practice questions
- CompTIA AI Fundamentals practice questions
- Google Cloud Generative AI Leader practice questions
- Oracle OCI AI Foundations practice questions
- CertNexus AIP-210 practice questions
- Anthropic CCAO-F practice questions
- Anthropic CCDV-F practice questions
- Anthropic CCAR-F practice questions
- Anthropic CCAR-P practice questions
- Databricks GenAI Engineer Associate practice questions
- Salesforce Agentforce Specialist practice questions
- CompTIA SecAI+ practice questions
- All AI & cloud exam prep →
Frequently asked questions
How much does the NVIDIA NCA-GENL exam cost?
$125 USD, taken online with remote proctoring.
How many questions is NCA-GENL and how is it scored?
50–60 multiple-choice questions in 60 minutes, scored pass/fail. NVIDIA does not publish a numeric passing score, so treat consistent 80%+ on timed practice as your readiness bar.
How long is the NCA-GENL certification valid?
2 years, then you retake the exam to recertify.
Do I need to code for NCA-GENL?
No — it is a conceptual multiple-choice exam. NVIDIA's stated prerequisite is a basic understanding of generative AI and large language models, and the exam tests concepts such as machine-learning fundamentals, embeddings, prompt engineering, RAG, experimentation, and trustworthy AI rather than whether you can write the code.